Tech Series · 14
Losing Your Data Is The One Bug You Can Never Fix
A bug in your code is a bad day. A wiped database can end the business — and a backup you have never restored is a guess, not a safety net.
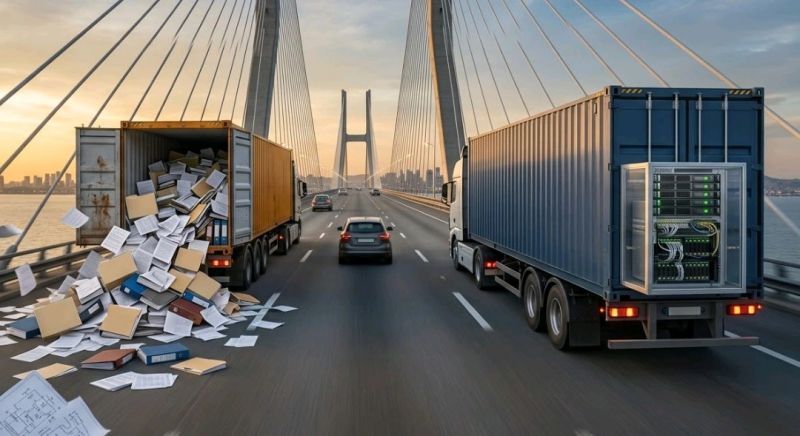
You obsess over code quality. You review pull requests, you write tests, you argue about naming.
Now answer one honestly. When did you last restore your database from a backup and watch the app come back up? Almost no founder ever has.
Code Breaks, Data Disappears
A bug in your code is a bad day. Someone reports it, you reproduce it, you push a fix. Painful, survivable, routine.
Losing your data with no way to bring it back can be the end of the business. Code can be rewritten in a week — you know what it did and why. A wiped customer database usually cannot be rewritten at all. Every order, every account, every message a user sent you is unique.
That asymmetry is the whole argument.
- Bugs are expected. Every app ships with them and you fix them as they surface.
- Data loss is not recoverable through effort. No amount of clever engineering brings back rows that are gone.
- A working restore removes the fear. You stop treating every deploy like a crisis, because the worst case is that you restore and move on.
What A Restore Test Is
Having backups is not the same as being able to recover. This is the part most teams skip. A nightly dump runs somewhere, nobody has ever opened it, and everyone assumes it works.
A real restore test is small and boring.
- Take the newest backup file your automation actually produced, not a fresh dump made for the test.
- Load it into an empty database on a throwaway machine.
- Point a copy of the app at it, log in, open a record, run a report.
- Time the whole thing from "we have a problem" to "the app works again".
- Note what is missing. Uploaded files, secrets, a table someone excluded two years ago.
That last step is where a first test usually fails. Teams back up PostgreSQL and forget the images in the folder beside it.
The 3-2-1 Rule
Three copies of your data, on two different kinds of storage, with one of them somewhere else.
Your live database is copy one. A dump on the same server is copy two, and it saves you from a bad query, not from the server dying. The off-site copy — another region, another provider, an AWS bucket the app never writes to — survives a deleted account, a failed region, or ransomware reaching everything it can touch.
RPO And RTO In Plain Words
Two terms worth knowing, because they turn a vague worry into a number you can decide on.
RPO, the recovery point objective, is how much data you are willing to lose. It is simply the gap between backups. Daily backups mean a bad morning costs you up to a day of orders.
RTO, the recovery time objective, is how long you can afford to be down while you restore. You do not estimate it. You measure it, and the restore test is the measurement.
How Often To Back Up
| Cadence | What a failure costs | Verdict |
|---|---|---|
| Daily | Up to one day of data | Do this if you can manage it |
| Weekly | Up to one week of data | The least you should accept |
| Less than weekly | Data you cannot get back | Gambling |
Then make one rule non-negotiable: a full backup and restore, run end to end, at least once a month. That is the bare minimum, and it is what turns the table above into a fact.
The Law Has An Opinion
Under laws like Saudi Arabia's PDPL (Personal Data Protection Law) and India's DPDP Act (Digital Personal Data Protection Act), losing data because you skipped basic safeguards is not just an operational failure. It can count as a compliance violation on its own, separate from any breach. Both laws deserve a piece of their own, and will get one.
Only Half The Danger
Everything above is about losing your data. Someone else getting into it without permission is a different danger, with different defences, and it deserves its own post. Losing your data is a disaster. Someone quietly reading it for six months before you find out is worse. That is a story for another piece.
A backup you have never restored is a guess, not a safety net.
So which one do you have — a tested restore, or a hope that the backup works?
Originally published on LinkedIn.
Was this useful?
Read the series — Tech Series
Tech Series index- 01Why DevOps (And What It Really Is)
- 02Zero to 100: Servers, Cloud, and Networking Foundations
- 03Cloud Under Fire: What Every Tech Leader Must Learn
- 04Why Big Tech Companies Still Go Down
- 05The Silent War Happening Inside Every Tech Company
- 06The Internet Was Never Designed to Be This Big
- 07Why the World's Most Expensive Software Keeps Failing
- 08AI Is Inside Your Pipeline. Most Teams Run It Wrong.
- 09The Japanese WordPress Hack: Zero To 100
- 10VPN: What It Is, Who It's Actually For
- 11Why "Full-Stack" Stopped Being Optional
- 13What Is System Design And Why You Should Care
- 14Losing Your Data Is The One Bug You Can Never Fix (this piece)
Muhammed Nasvih V
Lead DevOps Engineer & Technical Lead · Jeddah, Saudi Arabia
Writes The Stack Notes — field notes on infrastructure, AI, money and work. Cloud infrastructure, CI/CD, security and automation at Code7 Information Technology.
Comments
No comments yet — first word is yours.
Leave a comment
Comments are read before they appear, so yours will not show up straight away.